News
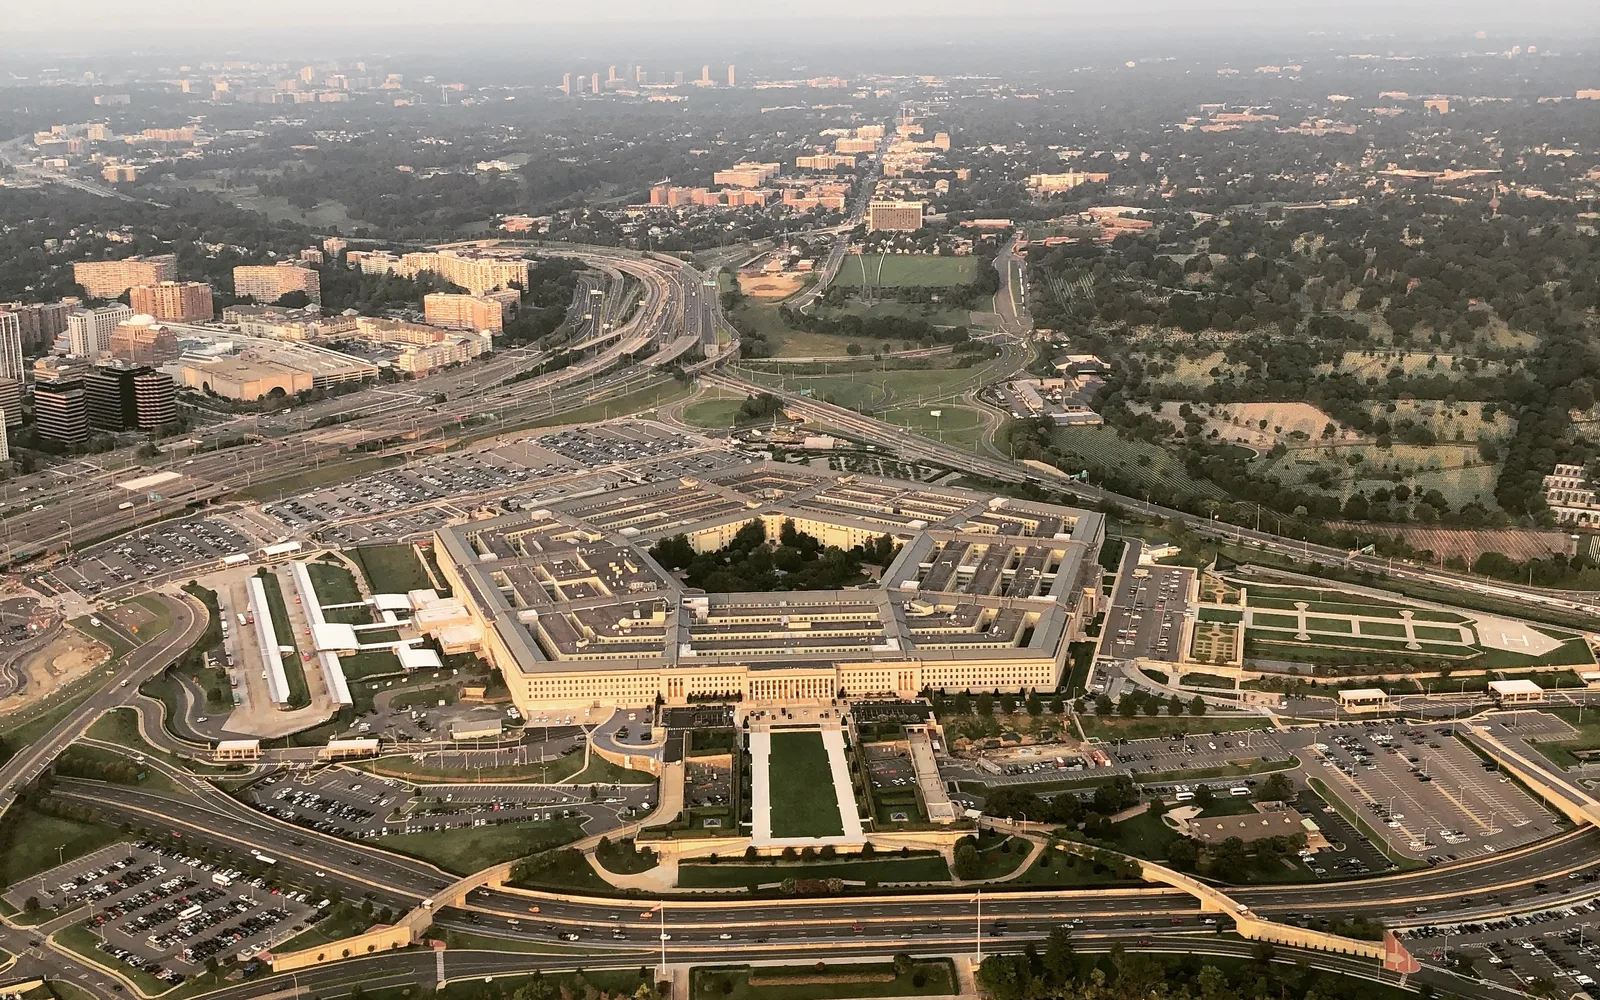
Pentagon Adds ChatGPT and Grok to GenAI.mil — Now Past 1.7 Million Users
The Pentagon's unified generative AI portal, GenAI.mil, has added OpenAI's ChatGPT Mil and xAI's Grok for Government, joining Google Gemini to offer three AI models.
A technical knowledge hub covering AI and Computer Vision
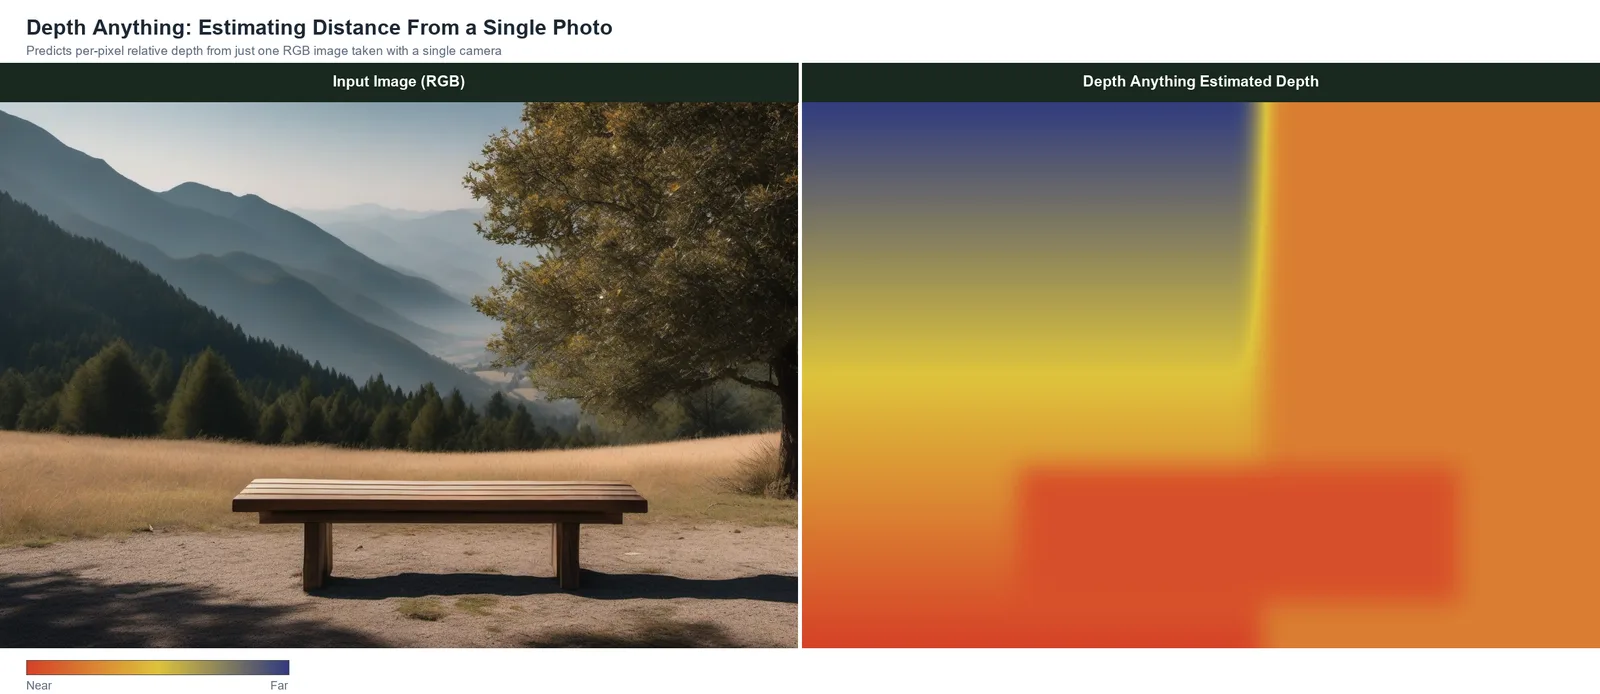
How Depth Anything, a monocular depth estimation model, predicts per-pixel relative distance from just one image taken with a single camera.
The Pentagon's unified generative AI portal, GenAI.mil, has added OpenAI's ChatGPT Mil and xAI's Grok for Government, joining Google Gemini to offer three AI models.
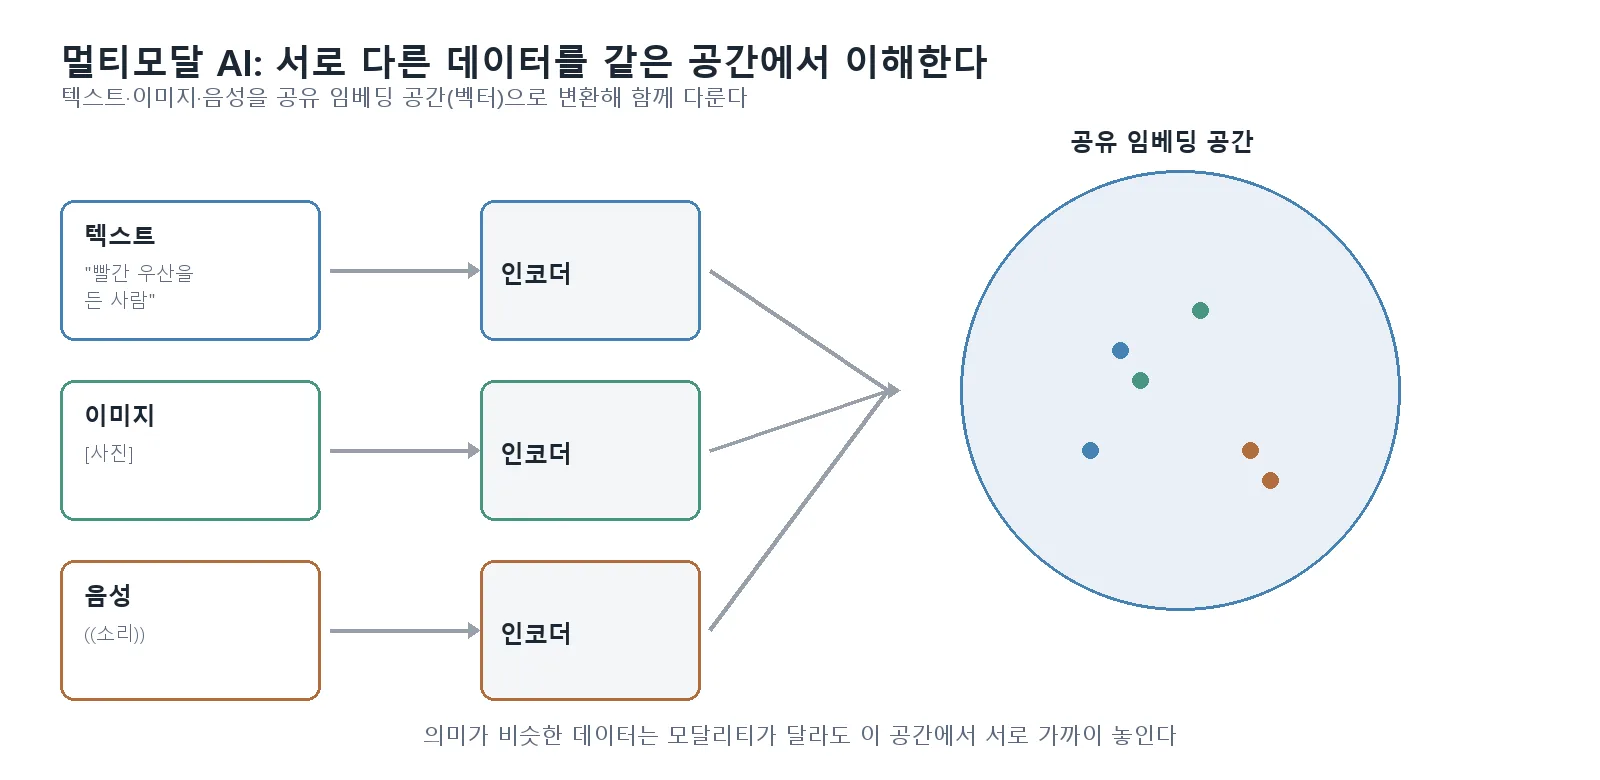
How multimodal AI lets a single model understand text, images, audio, and video at once, and the shared embedding space that makes it possible.
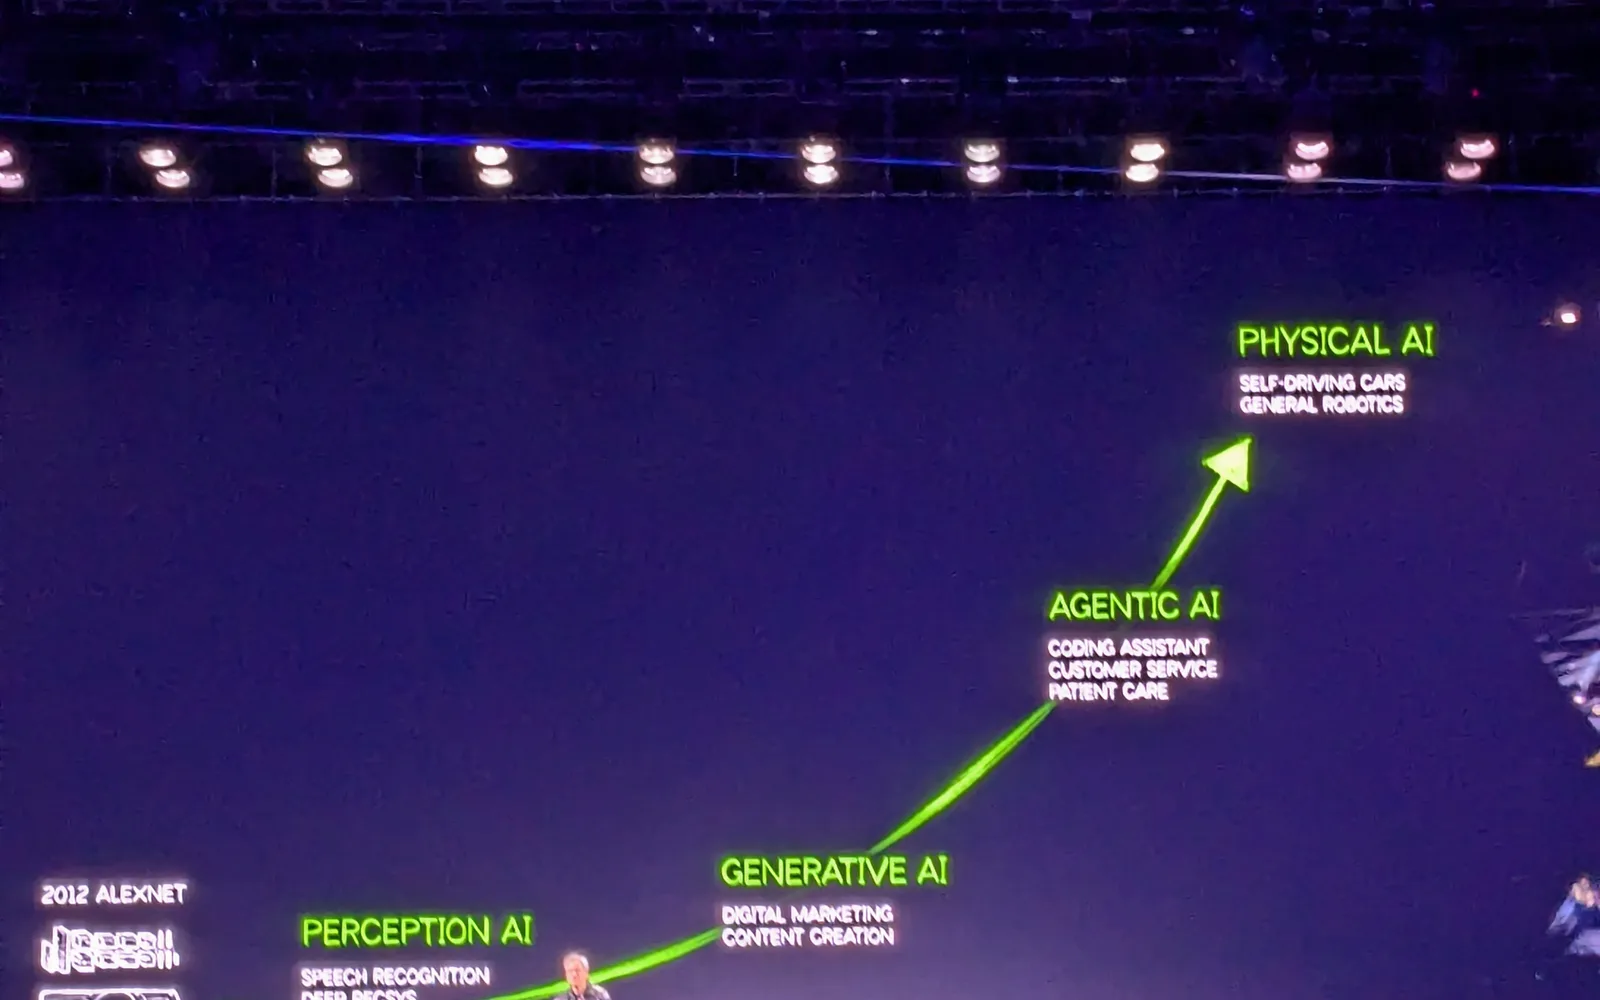
NVIDIA's Alpamayo, unveiled at CES 2026, is an open-source autonomous-vehicle VLA model that reasons through unfamiliar driving situations instead of just reacting to them.
Alibaba released Qwen3.8-27B under the Apache 2.0 license — a 27-billion-parameter native vision-language model that climbed into Hugging Face's most-liked models within two days of release.
Under Executive Order 14409, the US government has actually reviewed OpenAI's GPT-5.6 and Anthropic's Claude models. The process is voluntary, but access can still be restricted over national security concerns.
How multimodal AI lets a single model understand text, images, audio, and video at once, and the shared embedding space that makes it possible.
AIHow a Vector Database searches data by meaning rather than exact match, centered on the concepts of Embedding and similarity search.
AIAs GPU prices surge, GPU rental (Cloud GPU) services have emerged as an alternative. Here's how the different types work, what technology powers them, and how to actually use them.
AIHow the terms Agentic AI and AI Agent are actually used differently in practice, and why the distinction matters.
How Depth Anything, a monocular depth estimation model, predicts per-pixel relative distance from just one image taken with a single camera.
Computer VisionThe encoder-decoder architecture and prompt-based approach behind Meta AI's general-purpose segmentation model SAM, and how it evolved into SAM 2 and SAM 3.
Computer VisionThe core idea behind YOLO, which processes an image in a single forward pass to predict object locations and classes at once, and the architectural changes in the latest YOLO26.
Computer VisionYOLO and SAM solve different problems in computer vision. Here's how they compare, and when to reach for each one.