Computer Vision
What Is Segment Anything Model (SAM)? Segmentation Principles and Uses
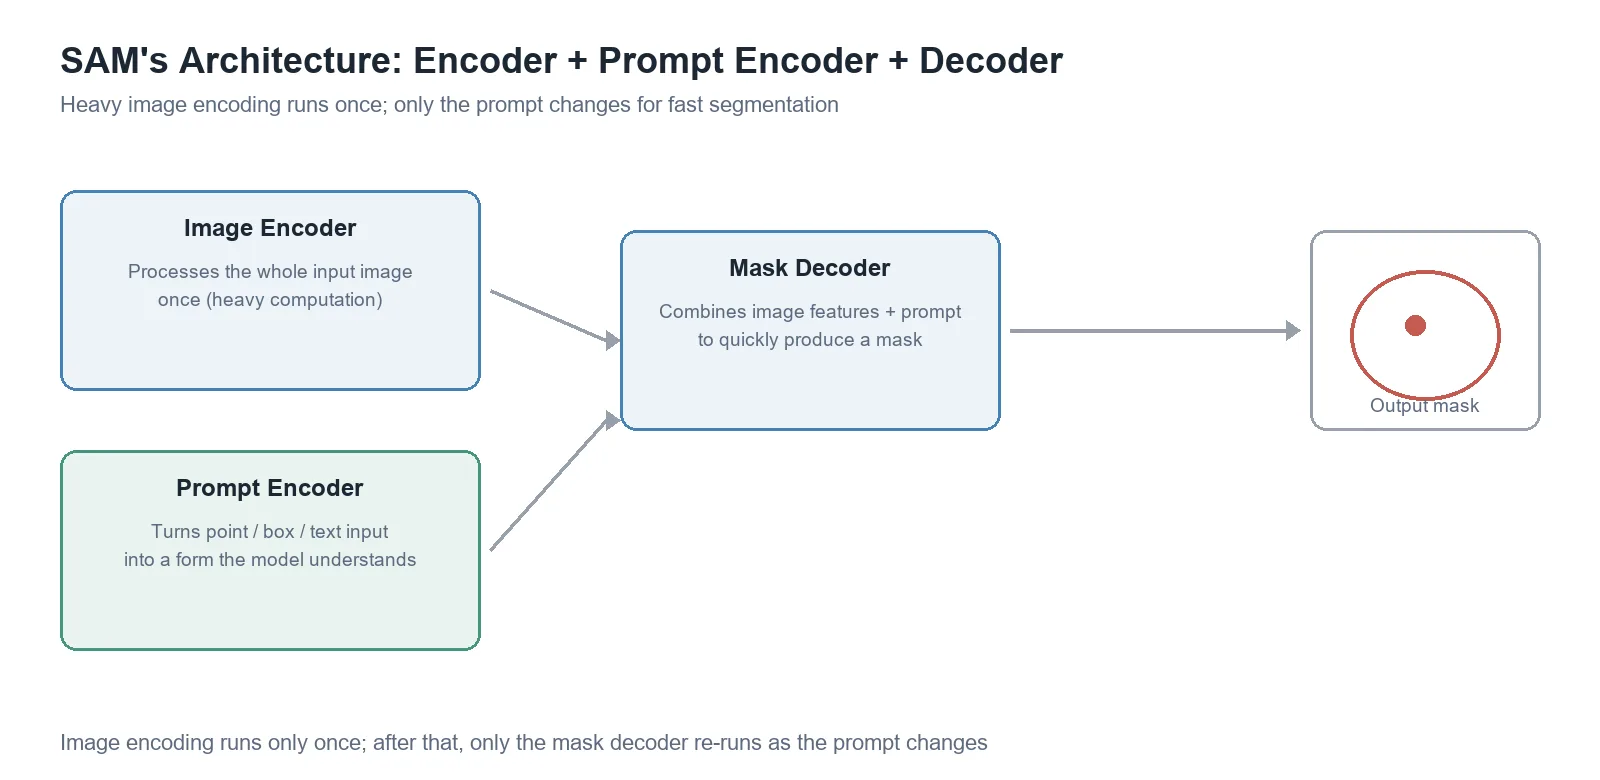
The encoder-decoder architecture and prompt-based approach behind Meta AI's general-purpose segmentation model SAM, and how it evolved into SAM 2 and SAM 3.
Covering the principles and applications of vision techniques: object detection, segmentation, depth estimation, and 3D reconstruction.
A technical knowledge hub covering AI and Computer Vision
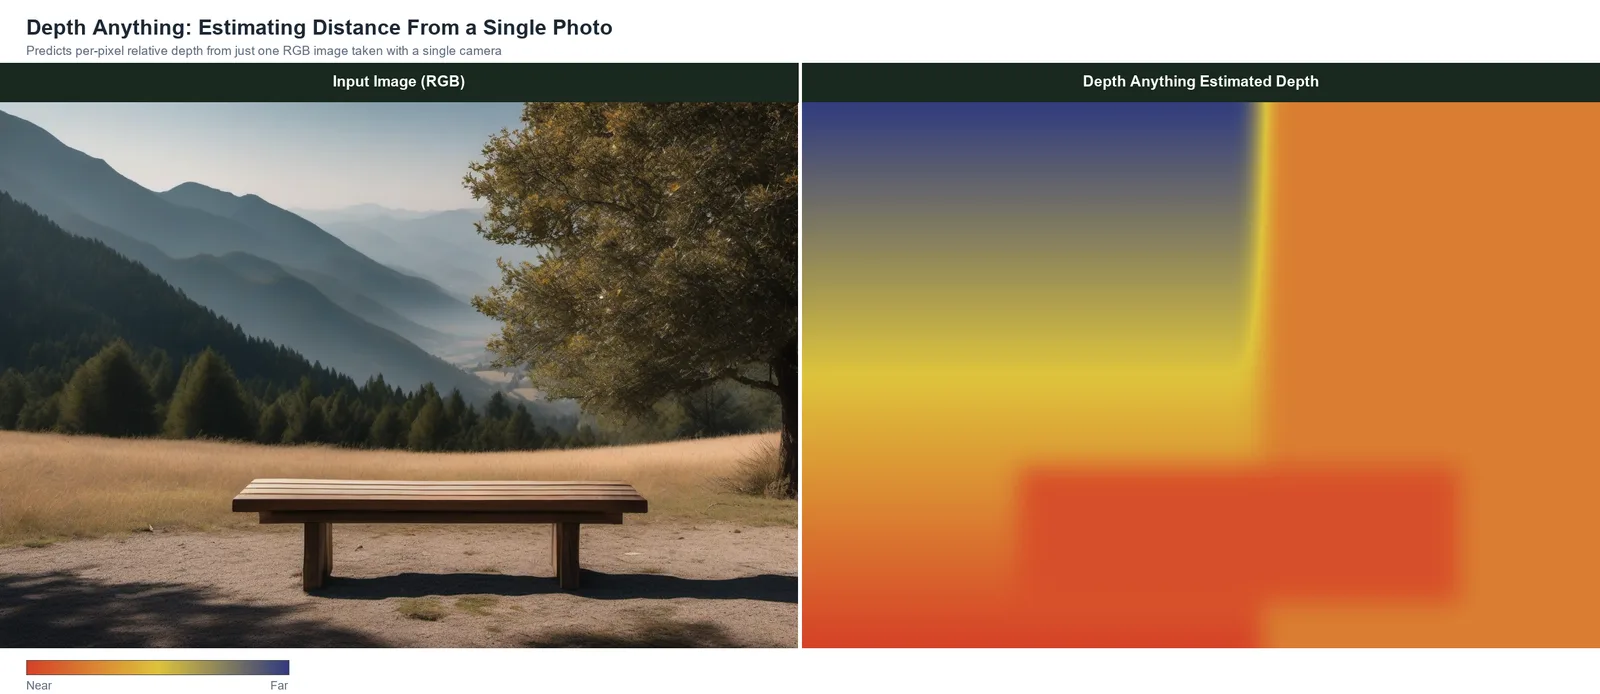
How Depth Anything, a monocular depth estimation model, predicts per-pixel relative distance from just one image taken with a single camera.
The encoder-decoder architecture and prompt-based approach behind Meta AI's general-purpose segmentation model SAM, and how it evolved into SAM 2 and SAM 3.
The core idea behind YOLO, which processes an image in a single forward pass to predict object locations and classes at once, and the architectural changes in the latest YOLO26.
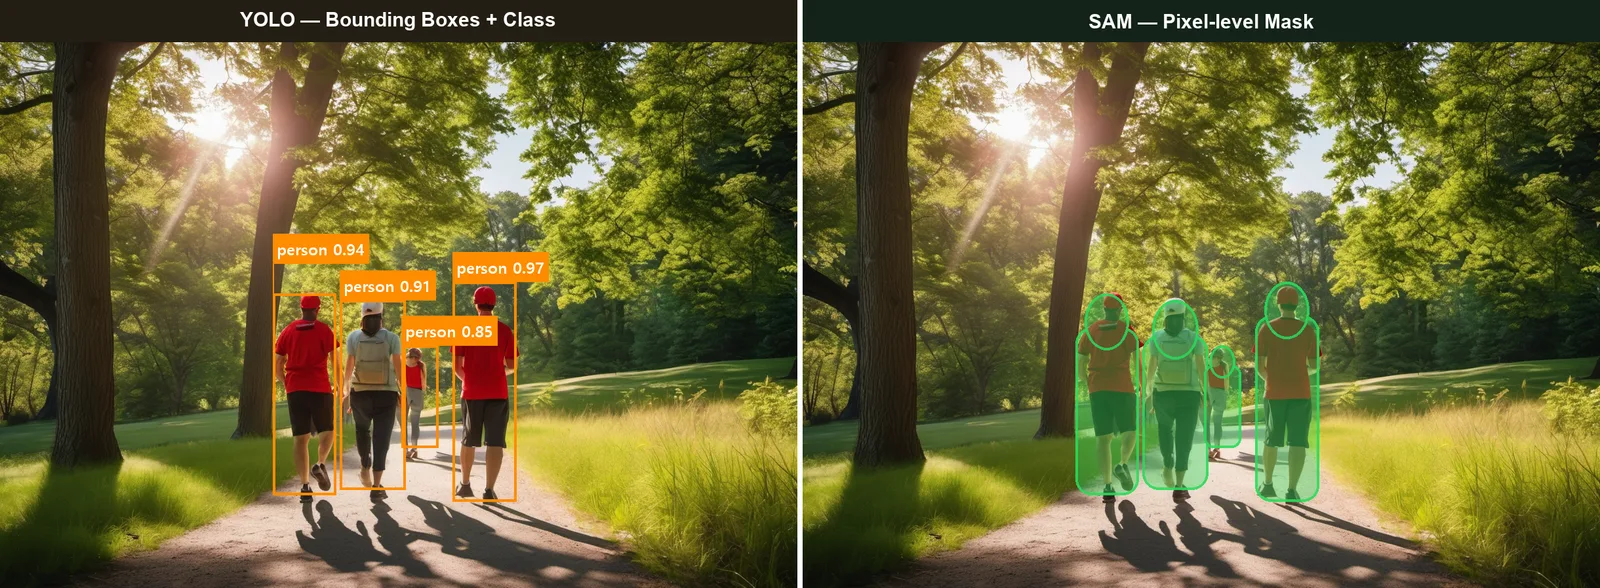
YOLO and SAM solve different problems in computer vision. Here's how they compare, and when to reach for each one.
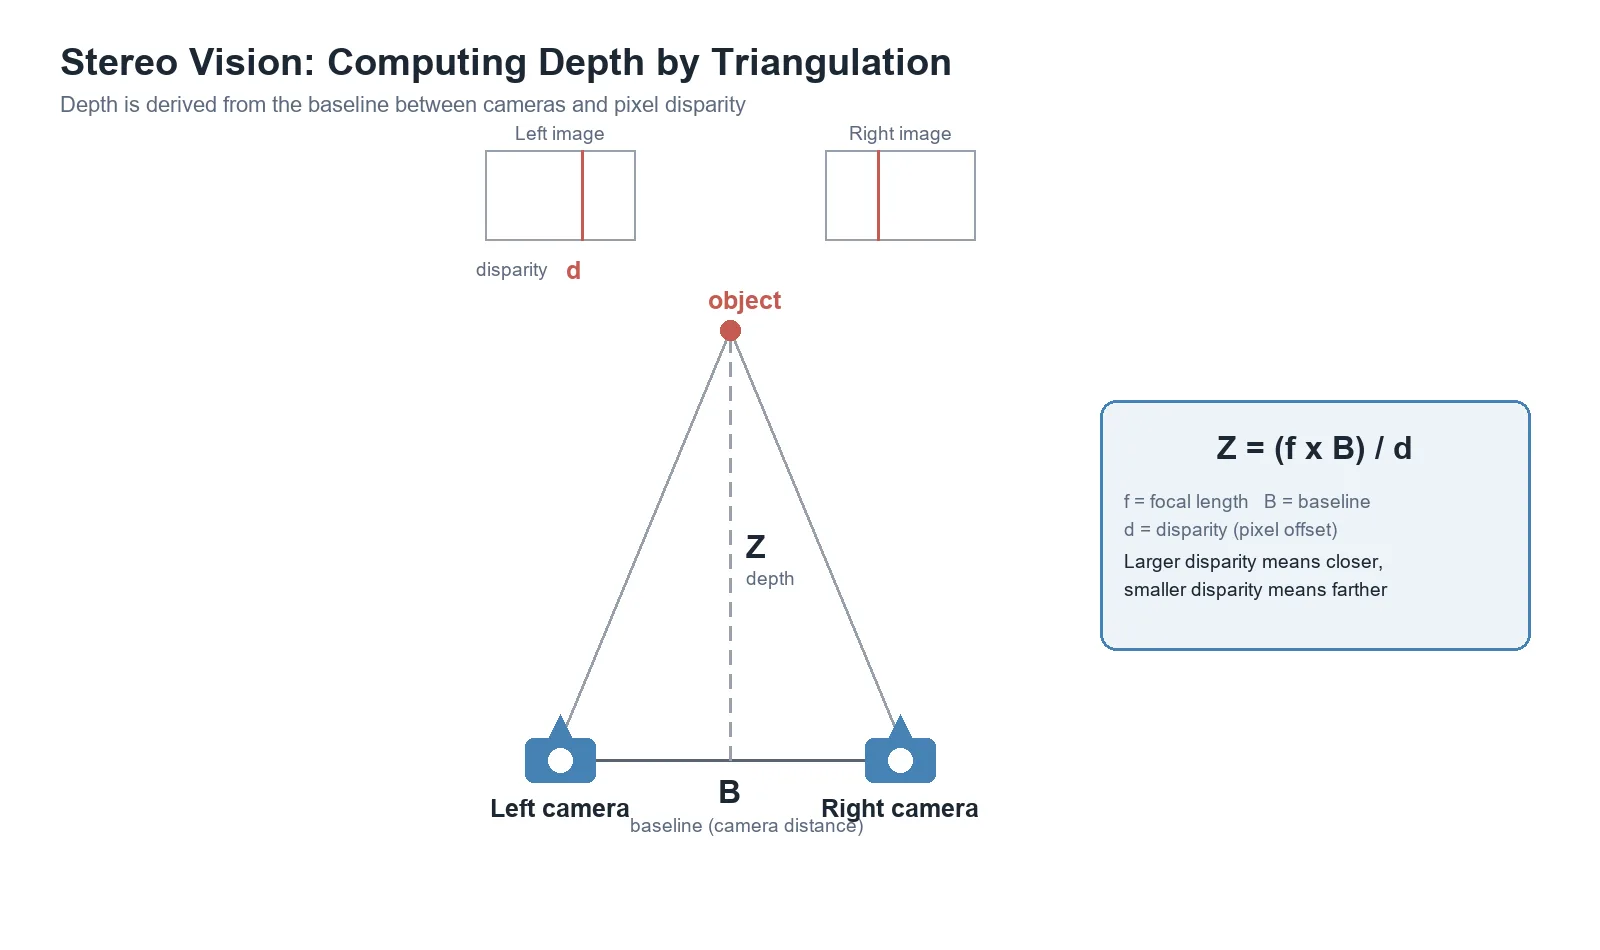
A walkthrough of the triangulation principle behind stereo vision, and the pipeline required to turn two camera images into depth.