What Is Physical AI? How It Differs from Generative AI
A breakdown of how Physical AI differs structurally from generative AI, and where it's actually used in robotics and autonomous systems.
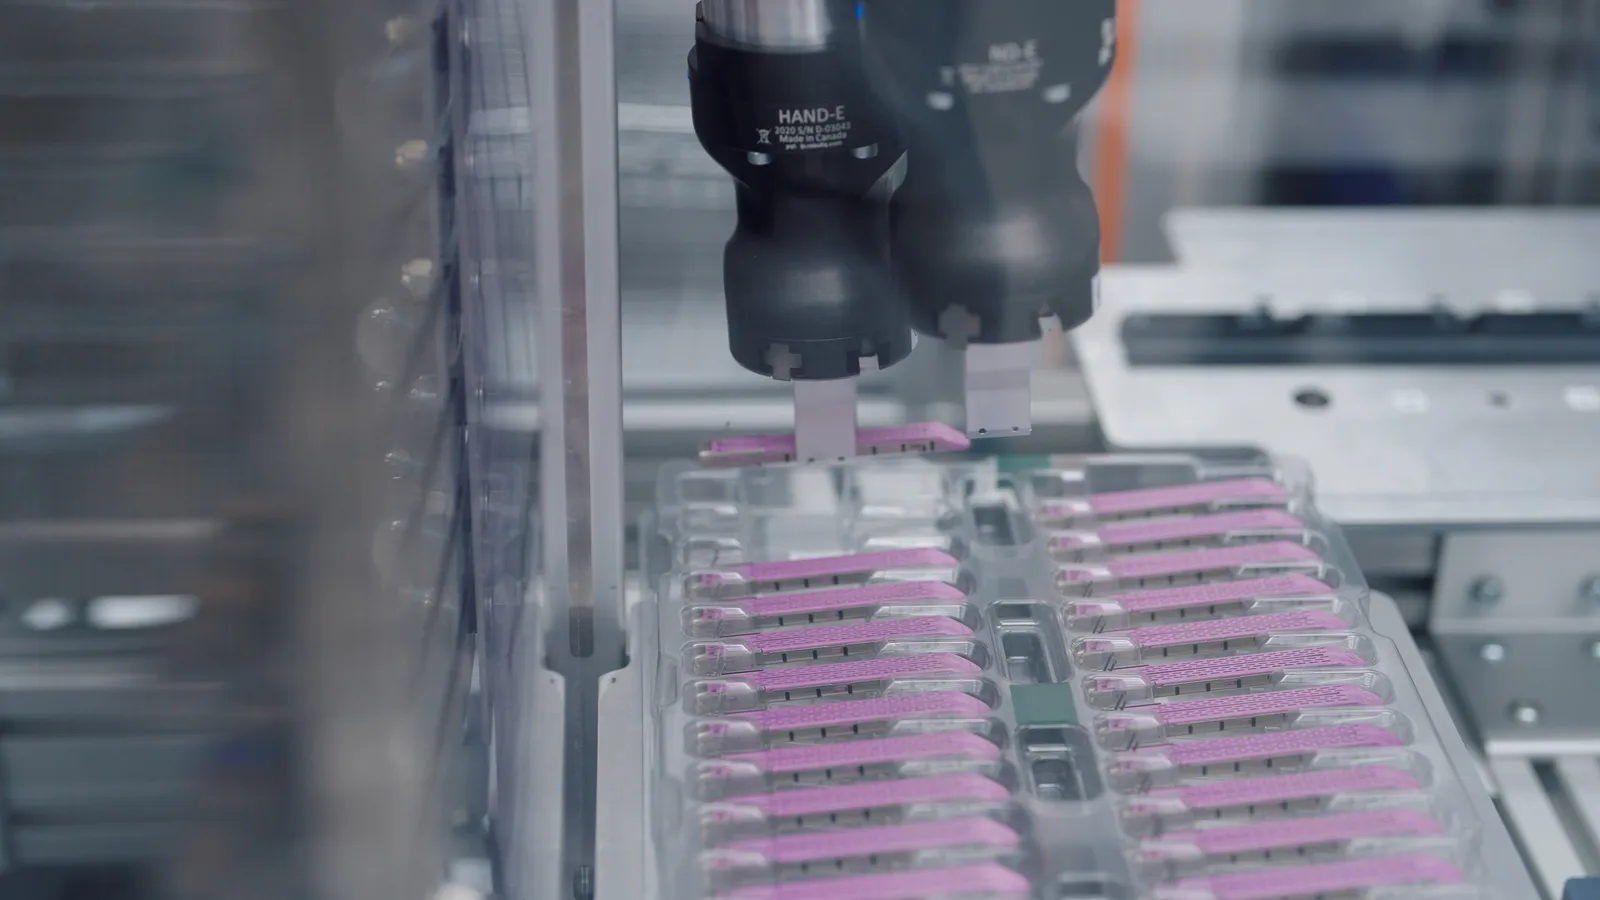
Physical AI doesn’t stop at generating text or images — it perceives the real world through sensors and acts on it physically through robots or machines. Where generative AI focuses on producing output “inside digital space,” physical AI runs a closed loop of perception, decision, and physical action. That loop is the key structural difference.
This article defines physical AI, contrasts it with generative AI, and covers where it’s actually deployed today.
What Physical AI Is
Physical AI systems repeatedly execute three stages:
- Perception — observing the environment through sensors such as cameras, LiDAR, and IMUs
- Decision — deciding the next action based on what was perceived
- Action — physically intervening in the real world through robotic arms, motors, or actuators
These three stages don’t run once — the result of each action is observed again by the sensors, and the loop repeats continuously. Because of this feedback structure, physical AI isn’t a static input-output model; it behaves more like an agent that interacts with its environment.
How It Differs from Generative AI
| Generative AI | Physical AI | |
|---|---|---|
| Input | Digital data: text, images, code | Sensor data: cameras, LiDAR, force sensors |
| Output | Digital results: text, images, audio | Physical motion via motors/actuators |
| Cost of failure | Bad text or image output | Potential physical damage — collisions, drops |
| Evaluation criteria | Output quality, coherence | Safety, accuracy, and response time in the real world |
| Core components | LLMs, diffusion models | Perception models + planning + control |
If generative AI makes a mistake, you just regenerate. If physical AI makes a mistake, real equipment or people can be harmed — which is why its safety and verification bar is far stricter.
Where It’s Actually Used
- Robotic manipulation: industrial and service robots that recognize and move objects
- Autonomous driving: perceiving surrounding vehicles and pedestrians via camera/LiDAR to plan a driving path
- Drones and autonomous vehicles: real-time obstacle avoidance and path planning
- Edge robot vision: low-power perception pipelines running on edge devices like Raspberry Pi or Jetson
Why Computer Vision Is a Core Component
The “perception” stage of physical AI is implemented almost entirely with computer vision techniques: object detection to locate nearby objects, segmentation to determine their precise boundaries, and depth estimation to calculate distance. In other words, physical AI isn’t complete with an LLM or generative model alone — it’s a system that combines computer vision, robotics, and control theory.
Limitations and Caveats
- Physical AI can be vulnerable to real-world uncertainty — sensor noise, changing lighting, and similar factors.
- Because physical actions are hard to undo, simulation-based verification matters a great deal.
- The term “physical AI” itself doesn’t yet have a fully standardized academic definition, and its scope can vary by company or community. The definition used here reflects the commonly accepted usage.
Conclusion
Physical AI adds sensor-based perception and real-world action to generative AI’s “digital output” capability. Its core is the perception-decision-action loop, and the perception stage in particular depends heavily on computer vision. Understanding physical AI means recognizing that AI and CV are converging rather than developing in isolation.